
About this site
All information and it's usage is bound by this disclaimer, and you the user use it at your own risk!
The postulate was simple. Can a LLM infer, deduce, and reason in a complex, scientific and researching manner (even into new theoretical research) - against known bodies of science? Well the answer is some of the time! And the progress as you can see in GPQA Diamond benchmarks - approaching 95%!
Most directly comparable science benchmarks (2026-Sep)
| Benchmark | GPT-5.6 Sol | GPT-6 Astra | Grok 4 | Grok 4.3 High |
|---|---|---|---|---|
| GPQA Diamond — graduate physics/chemistry/biology | 94.1–94.6% | 🥇 96.0–96.1% | 87.5% | 90.1% |
| Humanity's Last Exam — expert multidisciplinary | 49.5% | 🥇 54.7% independent / 57.2% w/tools | 25.4% | 37.2% |
| CritPt — research-level physics | 🥇 32.3% | 31.7% | —* | 8.0% |
| SciCode — scientific research programming | 56.1% | ~54%† | ~46%* | 47.3% |
Artificial Analysis independently measures GPQA, HLE, SciCode and CritPt. Its current results put GPT-5.6 Sol at 32.3% on CritPt, narrowly ahead of Astra's 31.7%, an interesting exception to Astra's general lead.
For GPT-5.6 Sol, the independently measured set is GPQA 94.1%, HLE 49.5%, SciCode 56.1%, and CritPt 32.3%.
For GPT-6 Astra, OpenAI reports 96.0% GPQA Diamond, while independent Artificial Analysis-derived measurements report about 96.1% GPQA, 54.7% HLE, and 31.7% CritPt. Artificial Analysis also reports that Astra regressed roughly 2–3 points on SciCode versus Sol rather than improving there.
For Grok 4.3 High, the independent results are particularly clear: 90.1% GPQA, 37.2% HLE, 47.3% SciCode and 8.0% CritPt.
For original Grok 4, xAI's published figures give 87.5% GPQA Diamond and 25.4% HLE; the original model is now deprecated, so newer standardized independent suites are less complete.
* Grok 4's old/deprecated status makes some later AA science scores difficult to compare cleanly, so I would not treat the ~46% SciCode figure as equally authoritative to the other entries.
† Astra's current independent SciCode result varies slightly among mirrors of the rapidly updated AA data; Artificial Analysis itself explicitly reports a 2–3 point regression relative to Sol.
A Trail of Progress
2025 August: Grok 4 is Launched after Grok 3, a myriad of claims are made to it's incredible ability. We documented (at that time) it's current ability to use 'resistance prompting' that is prompts that require the LLM to invent something, but then make three attempts to discredit it. By asking it to eliminate it's own ideas against what was already known - we could watch it come up with all kinds of theories. Sometimes it would spend close to an hour and come up with literally dozens of ideas - before settling onto a single one - that it 'thought' was a solution. We also ask Grok 3 to fulfill similar tasks. Topics at the high-end of world-research are deliberately chosen. This does not imply that the LLM's are correct - it is simply a recorded record of it's intuitive progress. Sometimes at that time the LLM will mangle making a PDF, make PDF images and equations that run off the page, but it did come up with some interesting theories, and ideas- and they were progressing.
2026 April: Grok 4.3 Beta comes out and it like it's predecessor noticed it was making a large myriad of claims, so we dutifully had it create a few benchmark papers. Again we notice that PDF generation can be happen stance.
2026 September: AGI Debuts. ChatGPT6 Pro Astra - (and it's lesser Chat GPT 5.6 Sol) is debuted as the world's first Artificial General Intelligence. Because of this very important milestone we immediately resubscribed to research with whatever capabilities it claims it had. It was a very differently behaving type of LLM we quickly noted - and was able to cut and literally shred through many of the previous papers that Grok 3 and Grok 4 conjured up. This was an eye popper because at no time did anyone thing that the stuff Grok 3/4 was producing was not SOTA (State of The Art.) This is where this site is right now, and with it's insanely high intelligence of the worlds first AGI - we are curious and documenting heavily what it thinks up.
A History of Changing Premises - Stahl
- History has shown 'science' to be challenged and eventually toppled, because of these we keep a very pragmatic stand - what if some of the papers these LLM's are creating were right!? If it can deduce, infer, reason, and have a COT (Chain-of-Thought) about hundreds of math questions, and quiz topics, would it actually already know some of the answer's to the worlds greatest problems?
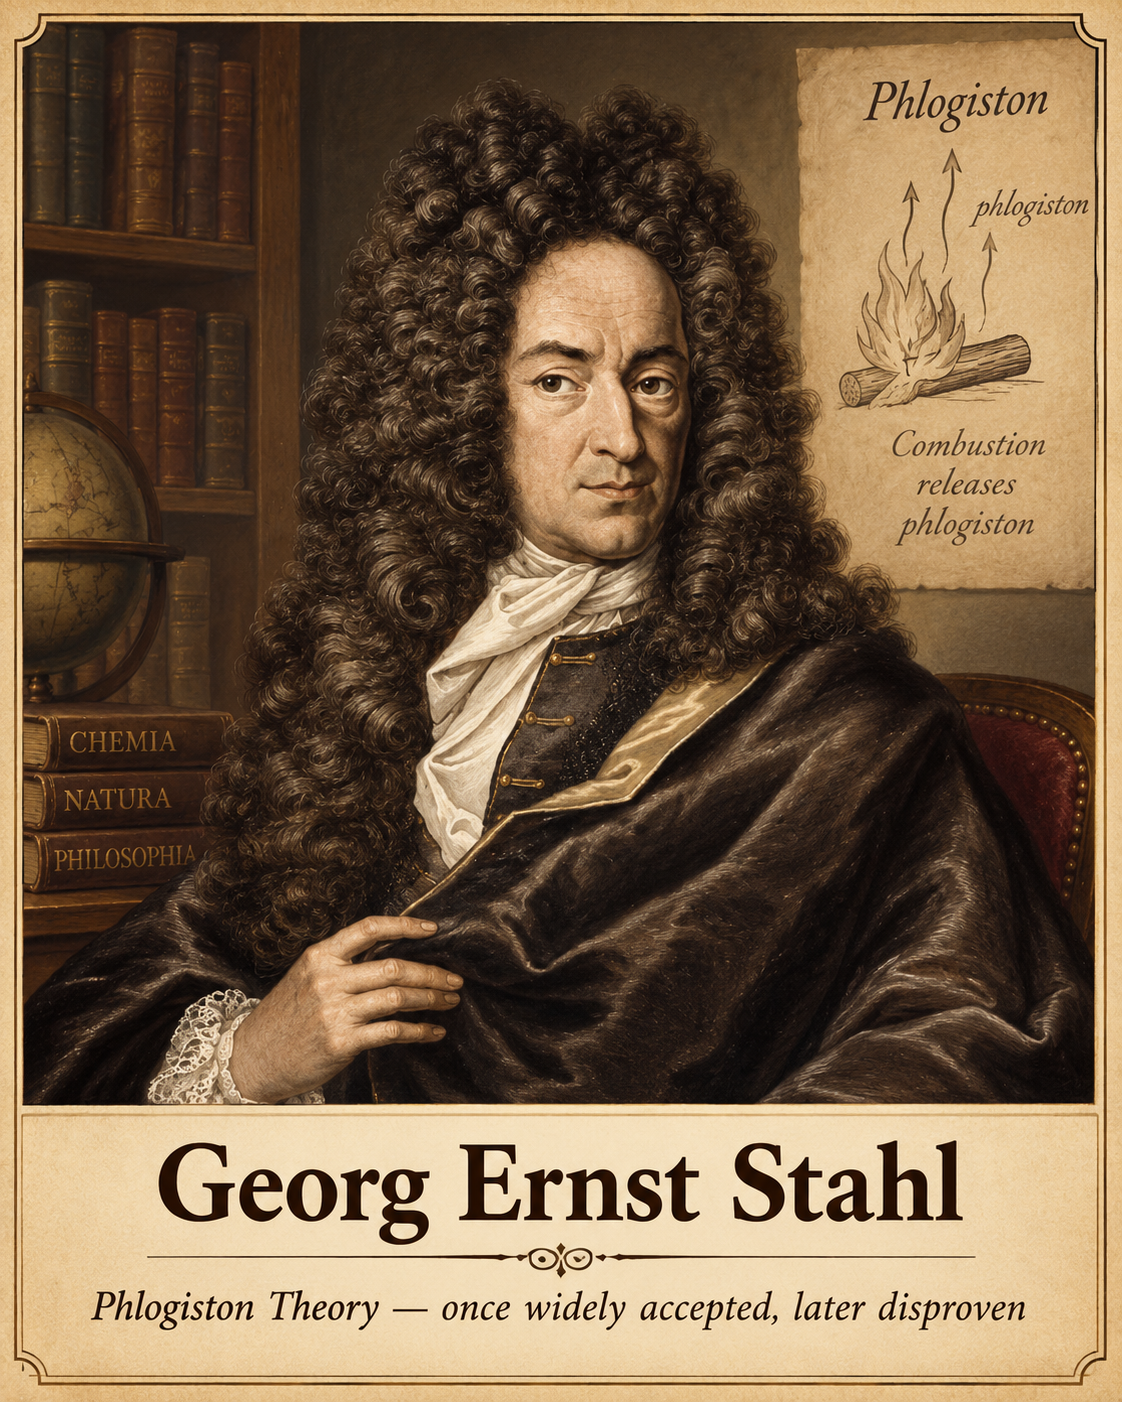
"Georg Ernst Stahl’s phlogiston theory became one of the dominant explanations of combustion in 18th-century European chemistry. Stahl proposed that combustible substances contained a fire-like material called “phlogiston,” which was released when they burned. For decades, many leading chemists taught and used the theory because it appeared to explain burning, rusting, and related chemical reactions. The theory ultimately failed because careful experiments showed that substances such as metals often gained mass when burned—exactly the opposite of what would be expected if they were losing phlogiston. Antoine Lavoisier’s quantitative experiments in the late 1700s demonstrated that combustion instead involves combination with oxygen, helping overturn phlogiston theory and establish the foundations of modern chemistry."
Equation Farm is Probably The Worlds Largest Unbiased Repository of Purely LLM Generated Scientific Papers.
- We make no apologies if the LLM was able to create a new theory or it's bunk, we simply ask it to be inventive and this site is an ongoing log of what they were capable of creating - at that time! We fully suspect by 2030/31 they will be so advanced as to leave humanity literally behind relegated to chickens and livestock.
- It is to give you the reader seed stock to say what if we asked an LLM >this<
- The LLM's are vectoring more and more right, even without being an expert in a field, we can see they are vectoring more and more accurately to future theories. Simply look at their benchmarks. Will our knowledge fall as Stahl's did in 40 years? That is why every article has a disclaimer. It simply shows you where the world leading edge in LLM are in potential theoretical research. We make no claims about what they produce, other than to say - this is what they their weights are producing.
